The Challenge
A financial services firm in India managed years of corporate filings stored as PDF documents—ranging from clean digital forms to faded, hand-scanned legacy records with complex multi-page financial tables. Operational teams manually retyped data by hand, spending several days per company to process and extract financial metrics.
The Choice
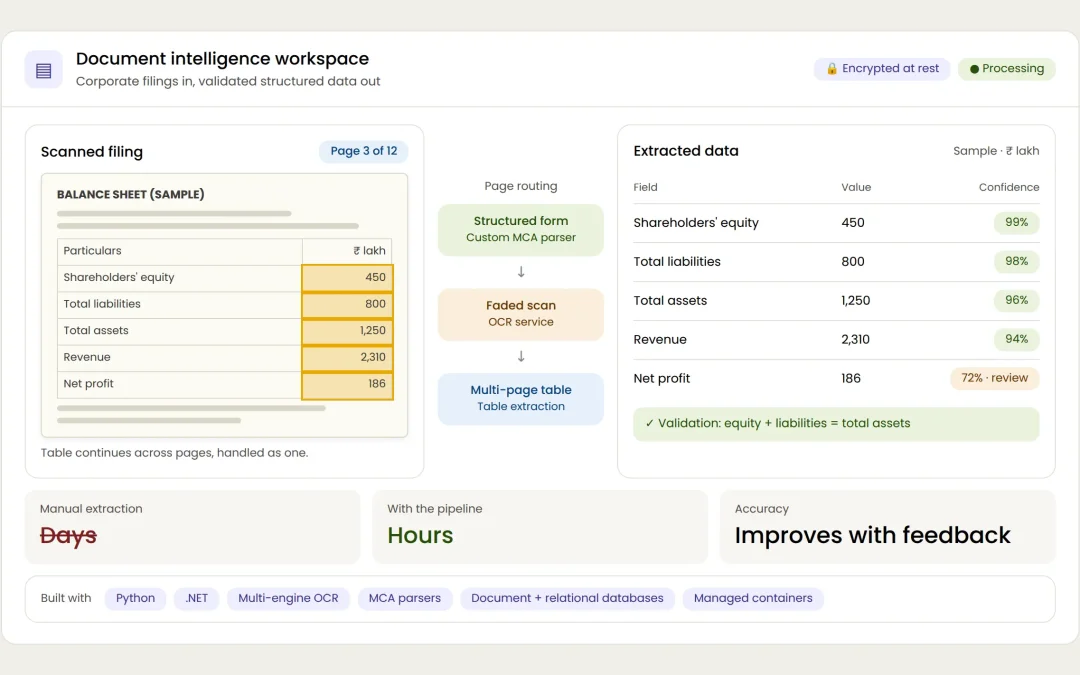
We recognized early on that relying on a single off-the-shelf OCR service would fail on complex or degraded scans. Rather than forcing a single tool or overcharging for speculative research, we committed to a fixed-price engagement: engineering a hybrid pipeline that intelligently routes each page to the optimal extraction reader based on document type and visual clarity.
What We Built
We engineered an enterprise document processing pipeline:
- Dynamic Multi-Reader Pipeline: Integrated external high-accuracy OCR services for handwriting and complex tables alongside custom .NET and Python parsers for structured MCA filings.
- Configurable Extraction Engine: Designed a flexible schema model where new document types can be configured on the fly without writing custom code.
- Containerized Deployment Architecture: Deployed services as isolated microservices running on a managed container platform with automated scheduling.
- Continuous Accuracy Refinement: Established continuous feedback loops that increased overall extraction accuracy from an initial 80% to higher, production-grade precision.
The Outcomes
- Tech Stack: Python, .NET, Managed Container Service, Relational Database, Document Database, Scheduler, External OCR APIs, Custom MCA Parsers.
- Compliance & Security: Financial records and extracted data are stored in encrypted databases with full encryption at rest.
- Operational Impact & Speed: Reduced financial data extraction timelines from a couple of days down to a couple of hours per company filing batch.
- Fixed-Price Partnership: Delivered on a transparent, fixed-price basis where Rite Technologies absorbed initial R&D and optimization costs—reflecting our long-term client commitment, where most of our partners rely on us for between 5 and 10 years across their core product lifecycles.
The Handover
By replacing manual data entry with an intelligent, multi-engine extraction pipeline, we transformed days of tedious manual typing into automated, high-accuracy data ingestion, empowering the firm to self-manage and scale document processing independently.
Tech Stack
Python
.NET
Document Intelligence
OCR
Managed Containers
Document Database
Relational Database
Encryption At Rest
MCA Filings
Fintech
Financial Services
If your financial team is processing large volumes of scanned document filings and needs automated data extraction,
let's connect.